KNOWS
Benchmarking web agents on synthesizing, organizing, and displaying knowledge
Findings of EMNLP 2026
Benchmarking web agents on synthesizing, organizing, and displaying knowledge
Findings of EMNLP 2026
Explore the code, tasks, and evaluators in the KNOWS GitHub repository.
We introduce KNOWS (Knowledge Navigation and Organized Web Synthesis), the first benchmark spanning live-web search, productivity tool use, and visual-spatial understanding. KNOWS consists of 110 open-ended and complex browser-based tasks that jointly evaluate these capabilities, with each task culminating in a produced artifact. Each artifact is a real Google Doc, Sheet, or Slide deck, built in the live Workspace interface. To write tasks, we develop a task design rubric and a protocol for ensuring that tasks meet the requirements. Each task is paired with an evaluator, a program that combines deterministic checks with LLM judgments to balance the richness, reliability, and automation tradeoff inherent to agent evaluation. In total, the creation of each task from start to finish took around 9–18 hours of expert work.
We evaluate and analyze frontier computer-use agents and browser-based harnesses on KNOWS, and find that the best performers fully succeed in 3.6% of our complex, long-horizon tasks. Failures on visual steps render the resulting artifacts unusable, even when agents complete more than 50% of other evaluation steps. Our results expose limitations of current agents acting as end-to-end assistants, and call for progress on tool use, visual understanding, and long-horizon reasoning.
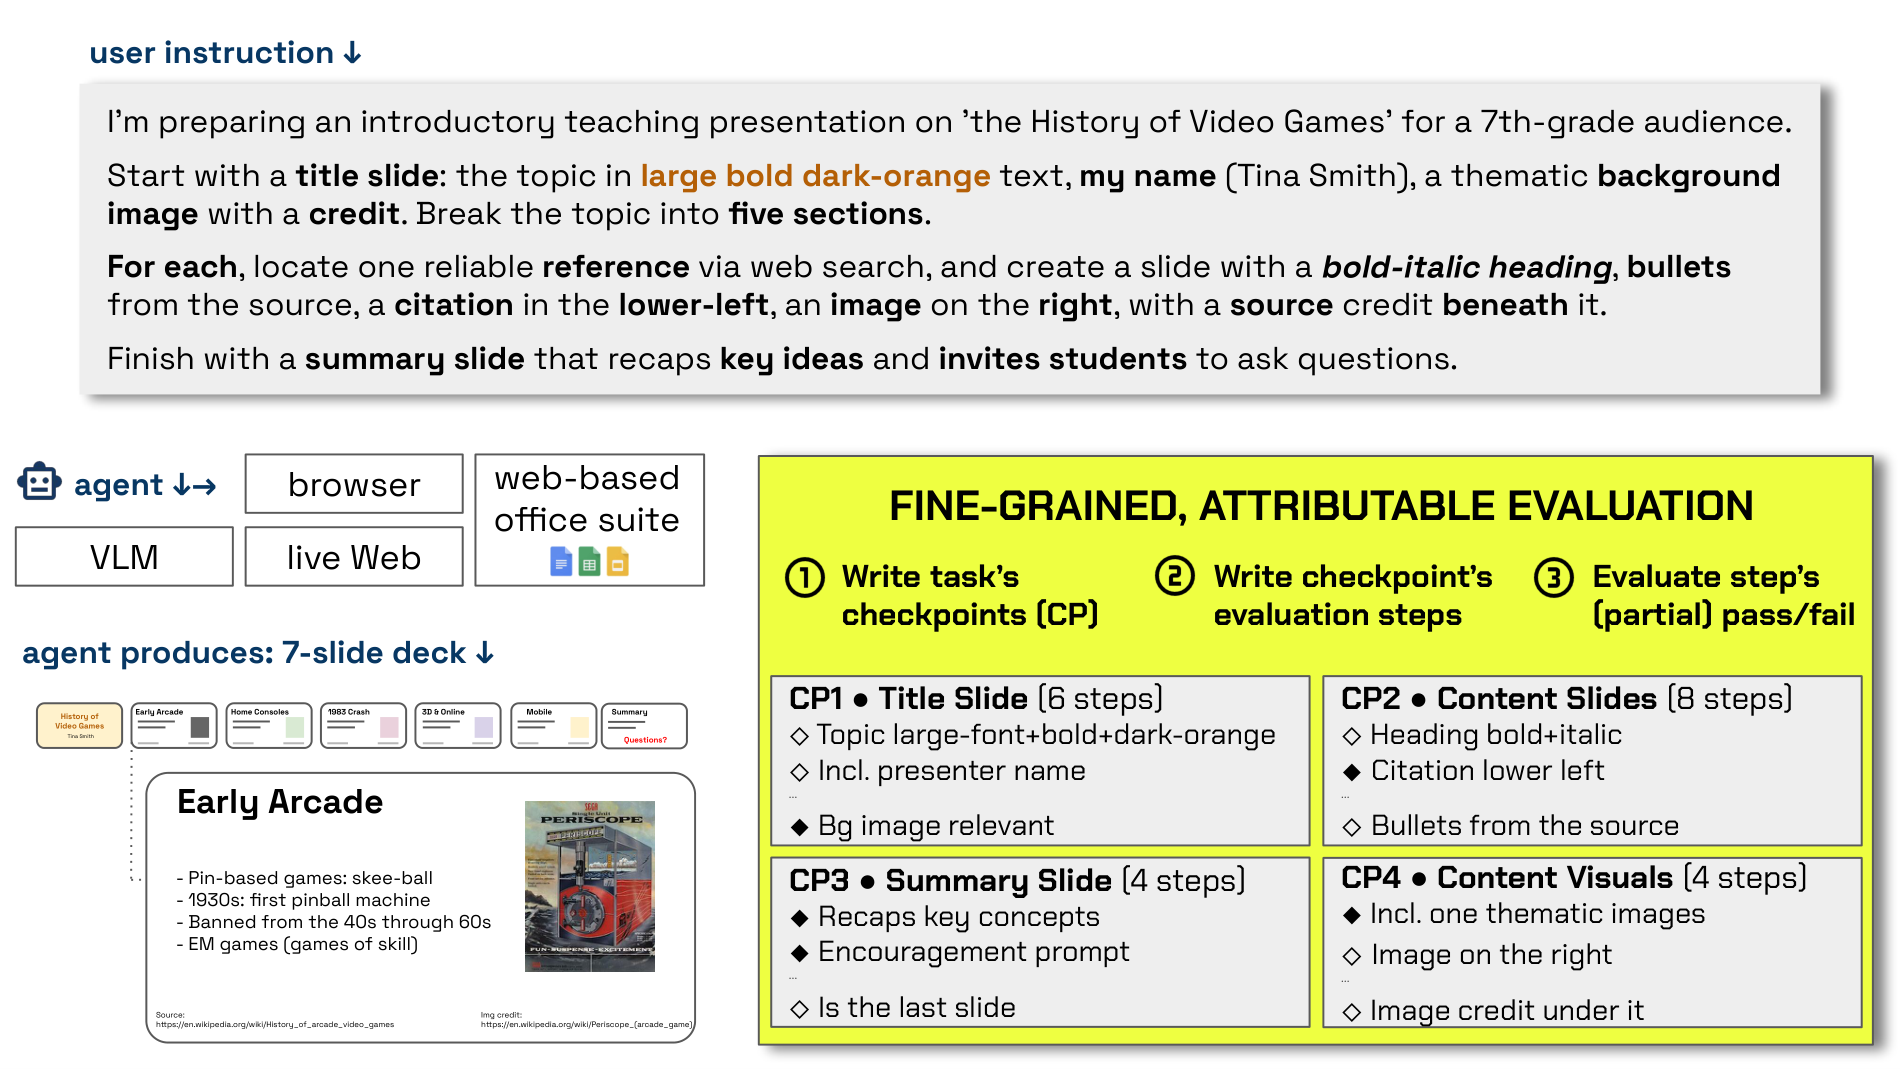
Below is an example of a single task in KNOWS, from prompt to evaluation.
| Rank | Model | Harness | Modality | Docs | Sheets | Slides | Overall | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| SR | ASC | ACF | SF | SR | ASC | ACF | SF | SR | ASC | ACF | SF | SR | ASC | ACF | SF | ||||
| 1 |  GPT-6 Astra |
Codex | AXT + SS | 16.0 | 38.0 | 62.4 | 55.2 | 0 | 46.5 | 77.3 | 75.3 | 0 | 40.5 | 73.4 | 66.0 | 3.6 | 42.4 | 72.5 | 67.4 |
| 2 | GPT-6 Luna |
Codex | AXT + SS | 16.0 | 26.3 | 47.0 | 42.7 | 0 | 25.2 | 51.3 | 48.0 | 0 | 17.0 | 44.9 | 39.3 | 3.6 | 22.5 | 48.0 | 43.6 |
| 3 |  Opus 4.7 |
Comet | Not specified | 12.0 | 41.0 | 68.7 | 66.3 | 0 | 35.8 | 73.0 | 68.3 | 0 | 31.3 | 67.5 | 59.7 | 2.7 | 35.4 | 70.0 | 64.7 |
| 4 | GPT-5.5 |
AgentLab | AXT + SS | 0 | 21.7 | 44.9 | 46.2 | 0 | 25.0 | 50.1 | 48.2 | 0 | 18.1 | 51.7 | 45.3 | 0 | 21.8 | 49.5 | 46.7 |
| 5 | GPT-5.5 |
Atlas | Not specified | 0 | 22.3 | 43.6 | 40.6 | 0 | 25.9 | 51.5 | 48.6 | 0 | 16.3 | 39.7 | 31.6 | 0 | 21.6 | 45.4 | 40.6 |
| 6 | GPT-5.5 |
AgentLab | AXT | 0 | 18.0 | 38.5 | 36.6 | 0 | 26.8 | 46.8 | 44.4 | 0 | 15.1 | 38.6 | 31.7 | 0 | 20.6 | 41.9 | 38.0 |
| 7 | Opus 4.7 |
AgentLab | AXT + SS | 0 | 21.3 | 47.3 | 49.0 | 0 | 11.4 | 28.8 | 24.8 | 0 | 19.7 | 54.8 | 48.9 | 0 | 16.7 | 42.5 | 39.1 |
| 8 |  DeepSeek V4 Pro |
AgentLab | AXT | 0 | 17.0 | 39.3 | 41.1 | 0 | 8.7 | 23.7 | 18.6 | 0 | 14.2 | 34.3 | 26.1 | 0 | 12.6 | 31.1 | 26.4 |
| 9 | Opus 4.7 |
AgentLab | AXT | 0 | 7.7 | 19.9 | 21.9 | 0 | 3.0 | 12.3 | 10.0 | 0 | 9.3 | 20.3 | 12.5 | 0 | 6.4 | 17.0 | 13.6 |
AXT: Accessibility tree (textual) · AXT + SS: Accessibility tree + screenshot (multimodal).
SR: Success Rate · ASC: Average Successful Checkpoints · ACF: Average Checkpoint Fraction · SF: Step Fraction.
A KNOWS’ task asks an agent to research something on the live web and turn what it finds into a finished Google Doc, Sheet, or Slide deck — satisfying content, formatting, and layout requirements at once. Every task is made of three parts.
Holding every task to that standard takes a deliberate process: a rubric of requirements, prompt creation with peer review, and a programmed evaluator written and debugged for each task.
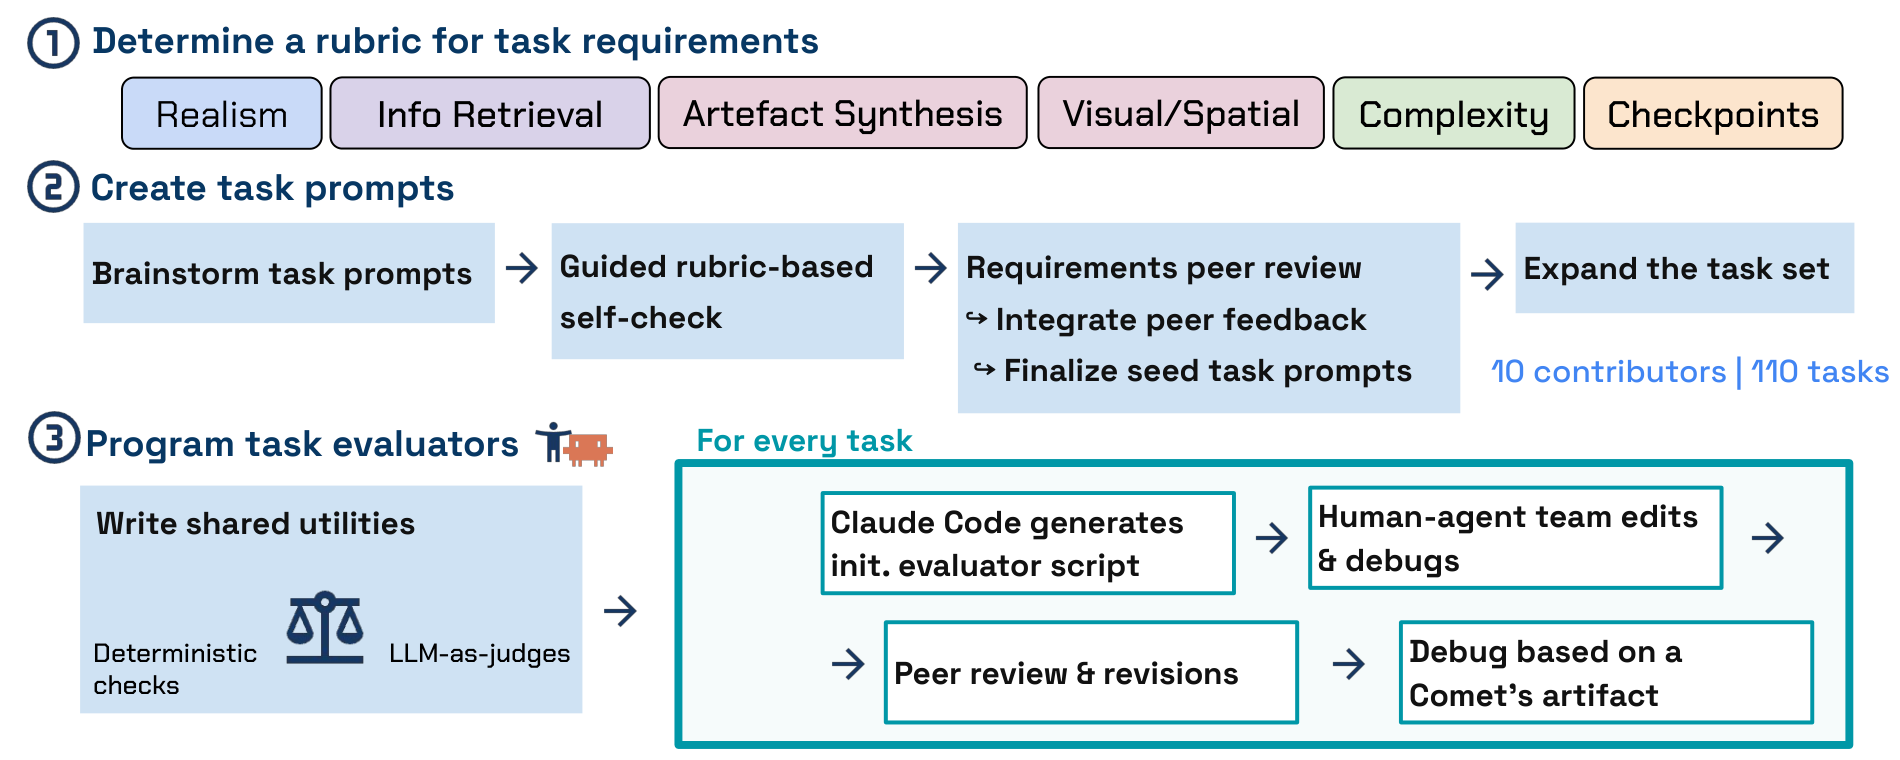
We translate our core design requirements into a rubric that guides task creation and keeps new tasks aligned with our motivation. Every task must satisfy all five.
Choose an artifact type and a domain to see a full task from that domain. The checkpoints on the right show every individual evaluation step, along with the type of check it performs.
Check types — select one for its definition and to highlight those steps.
For each evaluation step in a task, there is a verifier for the successful completion of that step. Each task has a dedicated evaluator script, which programmatically checks completion of each evaluation step, and returns completion scores for each checkpoint. Our evaluators are implemented by examining Google Workspace tool states, analyzing agent trajectories, and extracting data from the live web.
Many evaluation steps share common requirements in implementation, so we provide a suite of shared evaluation utilities available to any evaluator, organized around seven categories of evaluation step.
Below you can see how our evaluators grade expert-created “gold standard” artifacts, compared to how artifacts created for the same task by the browser agent Comet1, are graded.
1 Comet running a Claude Opus 4.7 agent.
We evaluate state-of-the-art computer-use agents across open-source and proprietary vision-and-language models and harnesses. Scores are reported per artifact type and overall, on four metrics ordered from strictest to loosest.
The leaderboard above reports all four metrics for Docs, Sheets, Slides, and overall.
We thank Google for providing funding for the construction of this benchmark. We thank Anthropic and OpenAI for their donation of API credits for benchmarking models. We thank Ivan Andhika, Matthew Lee, Ryhor Pryslopski, Spike Cheng and Qui Ngo for their contributions to the codebase, Shrusti Ghela and Ana Alvarez Lopez for providing valuable annotations, and everyone who consented to our use of their information in this benchmark. We also thank everyone involved in the review process for providing valuable feedback on KNOWS.
Placeholder — the final entry will be updated once the Findings of EMNLP 2026 proceedings are published.
@inproceedings{gill2026knows,
  title         = {The Hard Part Comes After Search: Benchmarking Web Agents on
                   Synthesizing, Organizing, and Displaying Knowledge},
  author        = {Gill, Alexander and Ishmam, Md Farhan and Nguyen, Xuyen and
                   Bhat, Neha and DeYoung, Parker Henry and
                   Hashemi Chaleshtori, Fateme and Stringham, Nathan and
                   Marino, Kenneth and Marasovi\'{c}, Ana},
  booktitle     = {Findings of the Association for Computational Linguistics: EMNLP 2026},
  year          = {2026},
  url           = {https://arxiv.org/abs/2609.30604},
  eprint        = {2609.30604},
  archivePrefix = {arXiv}
}